Key takeaways
- End-of-speech detection, transcription, first model token, first synthesised audio and outbound delivery each contribute a different delay.
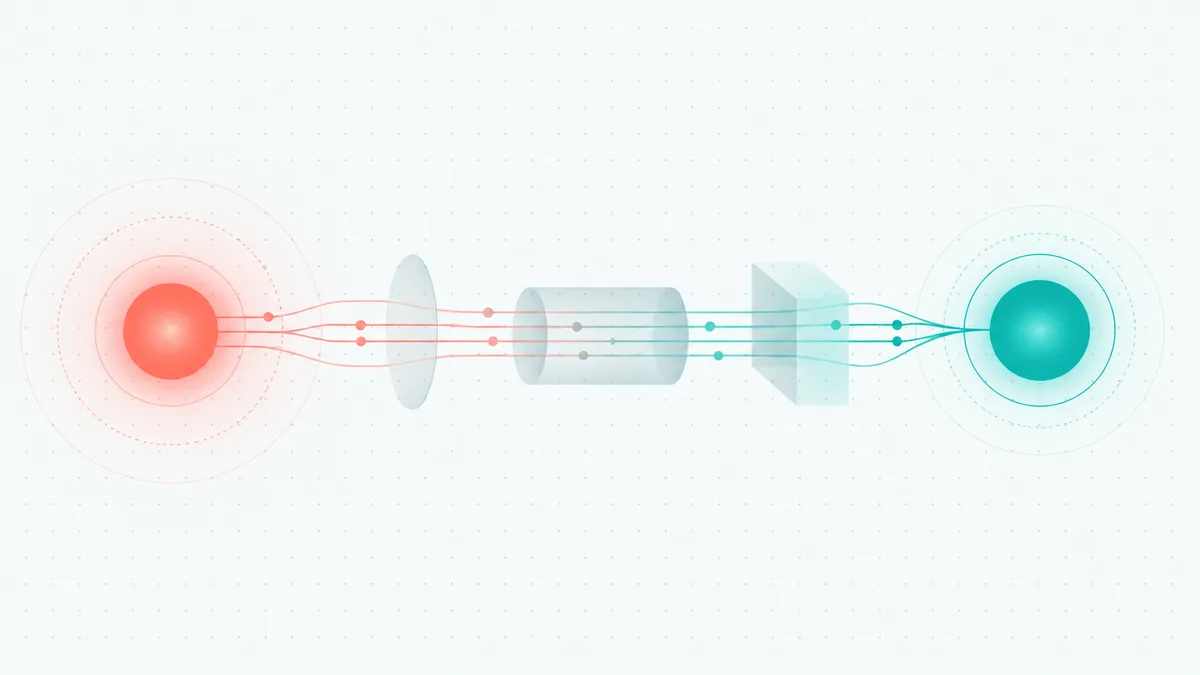
- When supported, sentence chunks can reach text-to-speech before the full model response finishes.
- Stopping playback is not enough.
- Provider readiness, disconnects, invalid audio and timeouts need distinct states.
Perceived latency is a chain
End-of-speech detection, transcription, first model token, first synthesised audio and outbound delivery each contribute a different delay. A single total hides where the experience is slowing down.
Streaming changes the shape of the turn
When supported, sentence chunks can reach text-to-speech before the full model response finishes. That makes chunk boundaries and cancellation behaviour part of product quality.
Caller stops talking
Speech becomes text
Reply starts forming
Voice starts speaking
Caller interrupts: speech stops, and it listens again
Barge-in must cancel downstream work
Stopping playback is not enough. Pending synthesis and queued audio should be cancelled so the next turn is not competing with stale work.
Measure failures truthfully
Provider readiness, disconnects, invalid audio and timeouts need distinct states. Accurate failure labels make both operations and customer support faster.